

Does Google Use LSI Keywords? The Truth About Semantic SEO
Discover whether Google uses LSI keywords and learn how modern semantic search actually works. Understand BERT, RankBrain, and entity-based optimization for bet...
11 min read
Latent semantic indexing (LSI) is a mathematical technique in natural language processing and information retrieval that uncovers hidden — or latent — relationships between words and documents.
On this page
Latent semantic indexing (LSI) is a mathematical technique in natural language processing and information retrieval that uncovers hidden — or latent — relationships between words and documents. Instead of matching exact keywords, LSI analyzes patterns of word co-occurrence across a collection of documents to infer what each document is actually about.
Breaking the name down makes the concept clearer:

Set up advanced tracking in minutes. No credit card required.
LSI works through a sequence of well-defined mathematical steps. Understanding them — even at a high level — clarifies why the technique matters and where its limits lie.
LSI starts by constructing a term-document matrix. Each row represents a unique term from the corpus, each column represents a document, and each cell records how many times that term appears in that document — or, more commonly, a weighted value such as TF-IDF (term frequency–inverse document frequency).
| Doc 1 | Doc 2 | Doc 3 | |
|---|---|---|---|
| car | 3 | 0 | 1 |
| automobile | 0 | 4 | 1 |
| engine | 2 | 3 | 0 |
| restaurant | 0 | 0 | 5 |
This matrix is typically large and sparse — most cells are zero because any given document uses only a small fraction of the total vocabulary.
The core mathematical operation in LSI is singular value decomposition. SVD breaks the term-document matrix into three smaller matrices:
A ≈ Uₖ Σₖ Vₖᵀ
By keeping only the top k singular values (and discarding the rest), LSI reduces the matrix to a much smaller, denser representation. This step removes noise, merges related terms, and surfaces the latent semantic structure. The choice of k is critical: too small and you lose meaningful distinctions; too large and you retain noise. In practice, k often ranges from 100 to 300 for moderate-sized collections.
Once documents and terms are mapped into the reduced semantic space, comparing them becomes straightforward. A query is projected into the same space, and its vector is compared to each document vector using cosine similarity — a measure that captures the angle between two vectors, with values closer to 1 indicating greater similarity.
The terms latent semantic indexing (LSI) and latent semantic analysis (LSA) are often used interchangeably, and for good reason: they describe the same underlying mathematical procedure. The distinction is one of application, not technique.
In short: LSA is the analysis technique; LSI is its application to search and retrieval. The original Deerwester et al. (1990) paper used the term “latent semantic indexing,” which is why the information-retrieval community adopted LSI, while the broader NLP and cognitive science communities tend to prefer LSA.
Be the first to know about new features and product updates.
LSI has been deployed in a range of real-world systems, particularly before the rise of neural-network-based approaches.
LSI was one of the earliest techniques to enable semantic search — retrieving documents based on conceptual relevance rather than keyword overlap. Early enterprise search systems, digital library catalogs, and academic research databases used LSI to improve recall: the proportion of relevant documents actually retrieved.
Because LSI maps documents into a shared semantic space, it naturally supports clustering. Documents on similar topics end up near each other in the reduced space, even if they share no exact vocabulary. This made LSI useful for automatic topic categorization, legal document review, and patent search.
One of LSA’s most cited applications outside of search is the Intelligent Essay Assessor, developed in the late 1990s. The system used LSA to compare student essays against a corpus of expert-written texts, producing scores that correlated well with human graders. This application demonstrated that LSA could capture something meaningful about textual content without any linguistic rules or domain-specific knowledge.
The original LSA research was partly motivated by questions in cognitive psychology. Landauer and Dumais showed that LSA could replicate aspects of human vocabulary acquisition and semantic priming effects, suggesting that the statistical structure of language exposure alone could explain significant portions of how people learn word meanings.
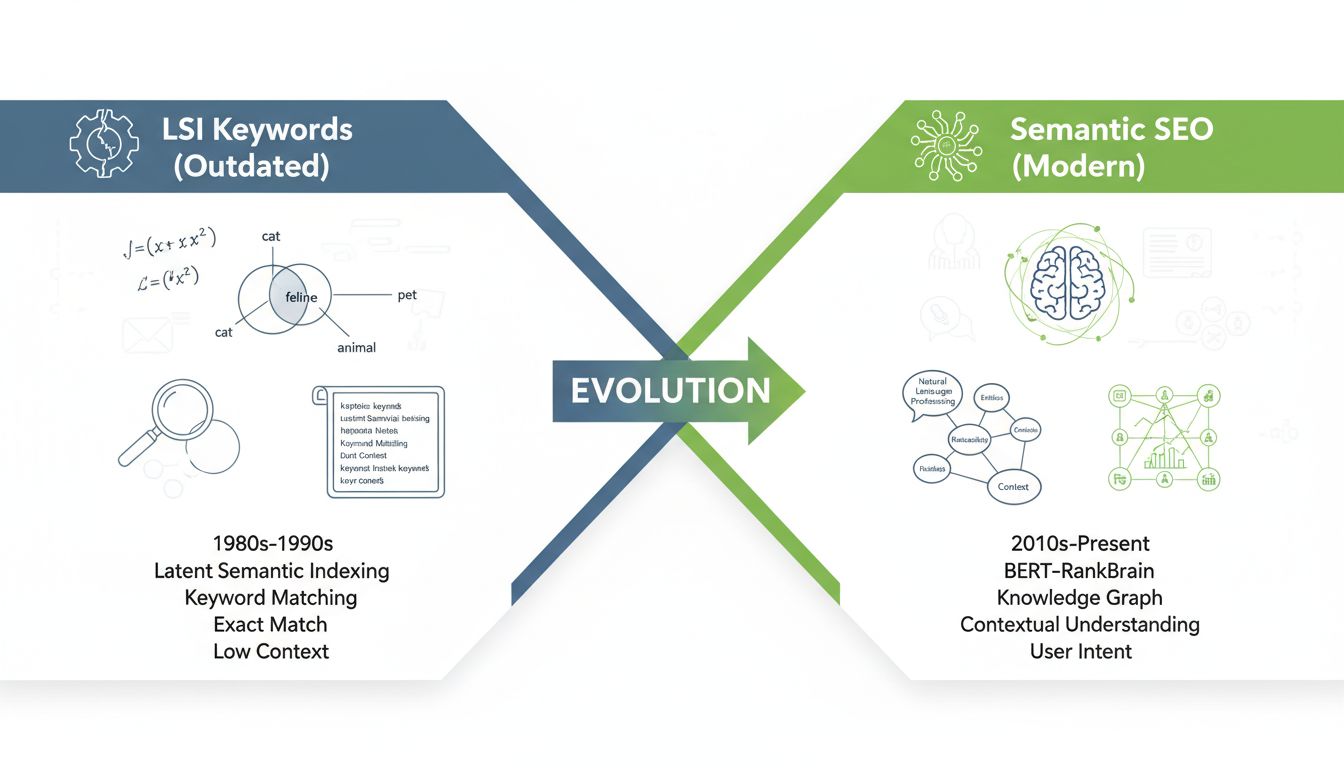
No. Google does not use latent semantic indexing in its ranking algorithms. This is not speculation — Google representatives have stated it directly.
The confusion has a historical root. In the early 2000s, as Google’s algorithm grew more sophisticated at understanding context, SEO practitioners looked for a framework to explain what they were observing. LSI — a real, published technique for semantic understanding — provided a convenient label. The idea that Google might use something like LSI to “see through” keyword stuffing and understand page topics was plausible enough to stick.
But Google’s modern approach to understanding content is far more advanced. Systems like RankBrain (introduced in 2015), neural matching, and BERT (2019) use deep learning and transformer-based architectures to model language. These systems process word order, context windows, entity relationships, and user interaction signals — none of which LSI handles. LSI is a linear-algebra technique operating on a static bag-of-words representation; Google’s infrastructure is orders of magnitude more complex.
In the mid-2000s, SEO tools and blogs began promoting the idea that Google used LSI to identify related terms and penalize pages that lacked semantic depth. The concept was attractive: it gave SEOs a scientific-sounding rationale for writing richer content and a checklist-style tactic (find your LSI keywords, sprinkle them in, rank higher). Tools emerged that claimed to generate LSI keywords for any topic.
The problem is that this narrative conflates two separate things: the mathematical technique called LSI, and the general practice of using related terms in content.
The underlying advice — write comprehensive, topically rich content — remains sound. The label is misleading.
In the strict technical sense: no. There is no algorithm within Google that takes a query, runs SVD on a term-document matrix, and returns a list of “LSI keywords” you should include on your page.
What does exist is the observable phenomenon that pages ranking well for a given query tend to use a broader vocabulary of related terms. This is a correlation, not evidence of an LSI-based mechanism. Modern search engines use neural language models trained on vast corpora to understand that “fuel efficiency,” “MPG,” and “hybrid engine” are all relevant to a page about cars — without ever building a term-document matrix or computing a single singular value.
If you are building a search system, a content recommendation engine, or any application that needs to understand semantic similarity between texts, the answer is clear: use embeddings.
LSI has a few niche advantages. It is transparent — you can inspect the term and document vectors and understand which dimensions contribute to similarity. It requires no training data beyond the document collection itself. It runs on modest hardware and can be implemented in a few dozen lines of Python using scikit-learn’s TruncatedSVD. For a small, static document collection — say, a few thousand product descriptions on an affiliate site — LSI can deliver acceptable results with minimal complexity.
Modern embedding models — whether sentence transformers like all-MiniLM-L6-v2, proprietary APIs from OpenAI or Cohere, or open-weight models — capture far richer semantic relationships than LSI ever could. They understand word order, negation, entity relationships, and cross-lingual semantics. They handle polysemy contextually: “bank” as a financial institution and “bank” as a river’s edge get different vector representations depending on surrounding words.
| Criterion | LSI | Modern Embeddings |
|---|---|---|
| Handles synonymy | Yes, partially | Yes, effectively |
| Handles polysemy | No (one vector per term) | Yes (contextual) |
| Captures word order | No (bag of words) | Yes |
| Training data needed | None beyond target corpus | Pre-trained on large corpora |
| Computational cost | Low | Moderate to high |
| Interpretability | High (inspectable dimensions) | Low (black-box vectors) |
| Best for | Small, static collections | Production search, RAG, recommendations |
For any project that will grow, serve real users, or need to understand nuanced queries, embeddings are the right choice.
Despite being superseded for large-scale search, LSI remains relevant in several specific contexts.
LSI is an excellent teaching tool. Its mechanics — building a matrix, decomposing it, and measuring similarity in the reduced space — make the abstract idea of “semantic similarity” concrete. Students who implement LSI from scratch come away with a genuine understanding of vector-space models that transfers directly to working with modern embeddings.
For a collection of a few thousand documents — internal wikis, product catalogs, legal contracts — LSI can be deployed quickly with no GPU, no API costs, and no model-serving infrastructure. The results are not state-of-the-art, but they are often good enough for internal tools and prototypes.
Researchers and engineers still use LSI as a baseline when evaluating new retrieval or topic-modeling techniques. If your fancy new neural model barely outperforms a 30-year-old linear-algebra method, you have a problem. LSI sets a useful floor.
Some enterprise search and document-management systems deployed LSI years ago and have no compelling reason to migrate. If the collection is stable, the query patterns are well-understood, and users are satisfied, replacing LSI with embeddings may be a solution in search of a problem.
If LSI is not a Google ranking factor and “LSI keywords” don’t exist, what should an affiliate marketer or program manager actually do? The answer is simpler — and more effective — than hunting for a magic keyword list.
The real insight behind the LSI-keyword concept is that pages covering a topic thoroughly tend to rank better. This does not require SVD. It requires understanding what questions your audience has and answering them. For an affiliate page reviewing fitness trackers, that means covering battery life, waterproof ratings, heart-rate accuracy, companion app quality, and price comparisons — not because an algorithm demands those terms, but because readers do.
Keyword research tools are valuable for discovering related queries, understanding search volume, and analyzing competitor content. Use them for that. Do not use them because they claim to generate “LSI keywords.” Google’s autocomplete, “People also ask” boxes, and “Related searches” at the bottom of the SERP are free and directly reflect real user queries — they are more useful than any third-party LSI tool.
Google’s modern approach to content understanding revolves around entities — real-world things, people, places, and concepts — and their relationships. When you write about a product, mention the brand, the category, the use case, the alternatives, and the relevant specifications. These are entities. Covering them naturally signals topical depth in a way that a machine-learning system can recognize, without any need for an obsolete matrix-decomposition technique.
LSI has well-documented limitations that explain why it was largely superseded.
LSI treats each document as an unordered collection of words. Word order, syntax, and grammatical structure are entirely ignored. “The dog bit the man” and “the man bit the dog” produce identical representations. For many real-world queries, this matters.
In LSI, each term gets exactly one vector — regardless of context. The word “bat” (animal vs. sports equipment) has the same representation in every document. Modern contextual embeddings solve this by producing different vectors for the same word in different contexts.
LSI builds its semantic space from a fixed document collection. Adding new documents requires recomputing the SVD — or at minimum projecting new documents into the existing space, which may not capture new vocabulary well. This makes LSI unsuitable for dynamic collections like news feeds or constantly updated product catalogs.
SVD is computationally expensive on large matrices. A term-document matrix for a web-scale collection would be intractable. The technique was designed for collections of thousands to tens of thousands of documents — orders of magnitude smaller than what modern search engines handle.
LSI cannot distinguish “good” from “not good” — both contain “good” in similar proximity to other terms. Sentiment, sarcasm, and fine-grained meaning distinctions are beyond its reach.
The phrase “LSI keywords” is often used loosely in SEO advice. A related word is not evidence that a search engine uses latent semantic indexing. For an affiliate comparison or product guide, cover the buyer’s actual questions and explain relevant concepts naturally; do not add a list of supposed LSI terms to chase rankings.
Discover how leveraging LSI and semantic keywords can improve your content’s search relevance and drive more organic traffic. Explore Post Affiliate Pro's solutions for affiliate marketers.
Discover whether Google uses LSI keywords and learn how modern semantic search actually works. Understand BERT, RankBrain, and entity-based optimization for bet...
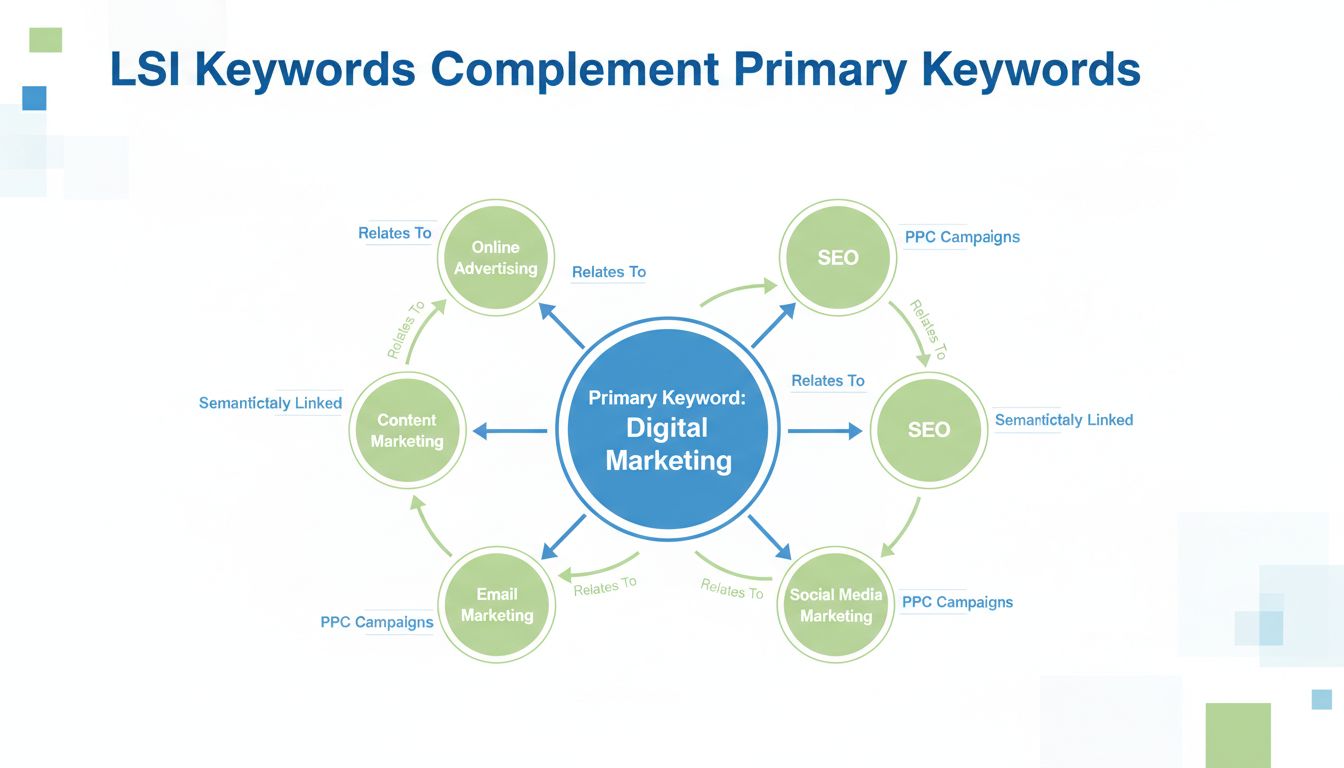
Learn why LSI keywords should complement, not replace, your primary keywords. Discover how semantic keywords enhance content relevance and improve SEO rankings ...
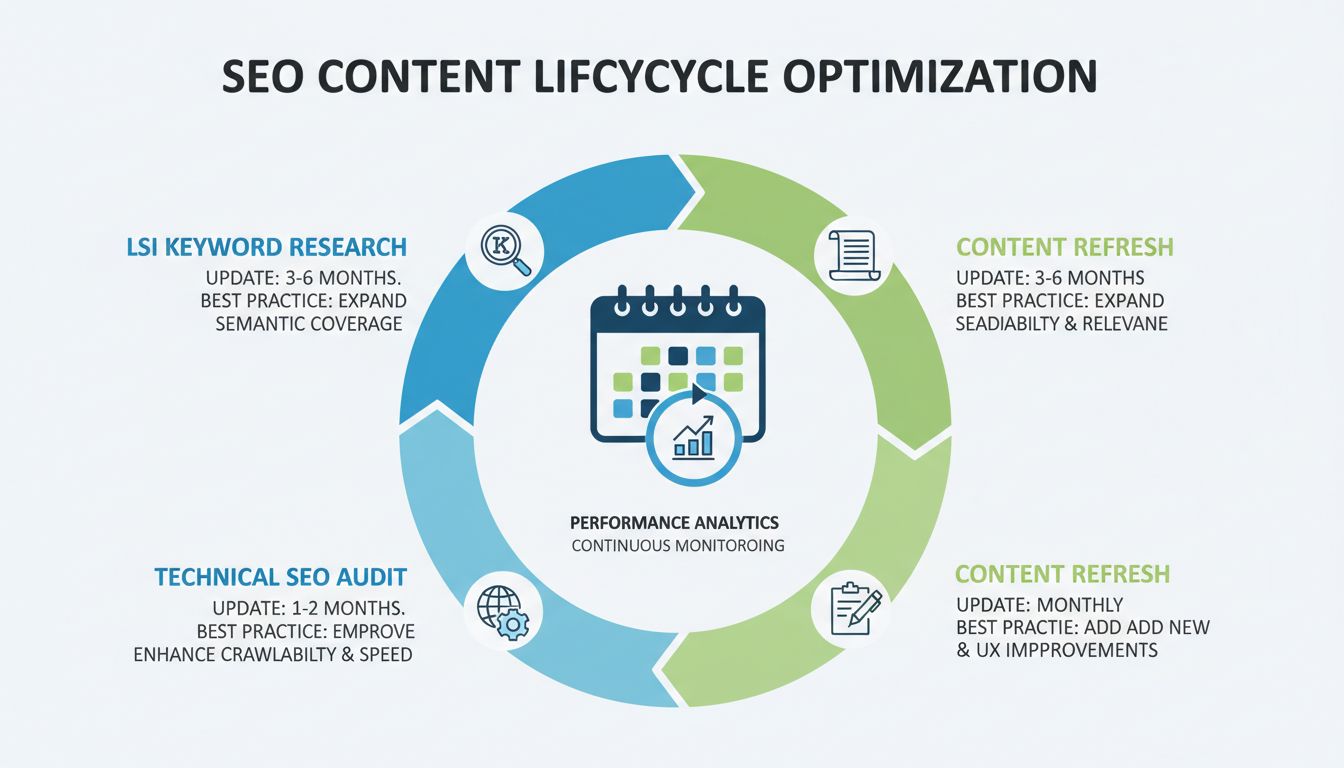
Learn the optimal frequency for updating content with LSI keywords. Discover best practices for keyword research, on-page optimization, and content refresh sche...
Join our community of happy clients and provide excellent customer support with Post Affiliate Pro.
Cookie Consent
We use cookies to enhance your browsing experience and analyze our traffic. See our privacy policy.